大家好,我是讯享网,很高兴认识大家。
1. Beautiful Soup的简介
https://www.jb51.net/article/65287.htm
简单来说,Beautiful Soup是python的一个库,最主要的功能是从网页抓取数据。官方解释如下:
Beautiful Soup提供一些简单的、python式的函数用来处理导航、搜索、修改分析树等功能。它是一个工具箱,通过解析文档为用户提供需要抓取的数据,因为简单,所以不需要多少代码就可以写出一个完整的应用程序。
Beautiful Soup自动将输入文档转换为Unicode编码,输出文档转换为utf-8编码。你不需要考虑编码方式,除非文档没有指定一个编码方式,这时,Beautiful Soup就不能自动识别编码方式了。然后,你仅仅需要说明一下原始编码方式就可以了。
Beautiful Soup已成为和lxml、html6lib一样出色的python解释器,为用户灵活地提供不同的解析策略或强劲的速度。
废话不多说,我们来试一下吧~
2. Beautiful Soup 安装
Beautiful Soup 3 目前已经停止开发,推荐在现在的项目中使用Beautiful Soup 4,不过它已经被移植到BS4了,也就是说导入时我们需要 import bs4 。所以这里我们用的版本是 Beautiful Soup 4.3.2 (简称BS4),另外据说 BS4 对 Python3 的支持不够好,不过我用的是 Python2.7.7,如果有小伙伴用的是 Python3 版本,可以考虑下载 BS3 版本。
?
| 1 |
sudo apt-get install Python-bs4
|
如果想安装最新的版本,请直接下载安装包来手动安装,也是十分方便的方法。在这里我安装的是 Beautiful Soup 4.3.2
?
| 1 |
Beautiful Soup 3.2.1Beautiful Soup 4.3.2
|
下载完成之后解压
?
| 1 |
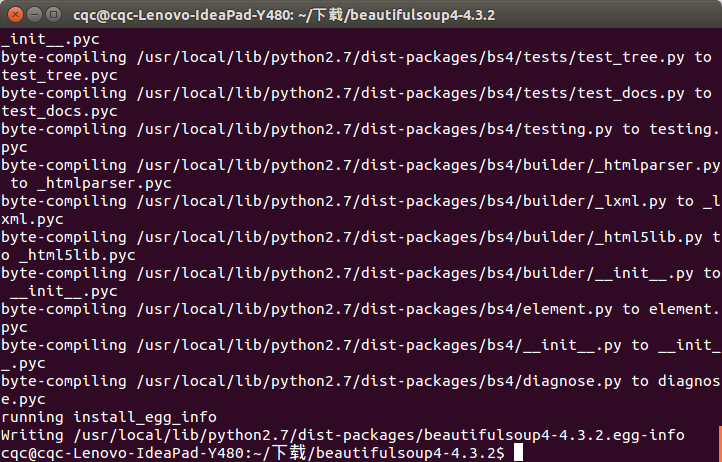
sudo python setup.py install
|
如下图所示,证明安装成功了

讯享网
?
| 1 |
sudo apt-get install Python-lxml
|
Beautiful Soup支持Python标准库中的HTML解析器,还支持一些第三方的解析器,如果我们不安装它,则 Python 会使用 Python默认的解析器,lxml 解析器更加强大,速度更快,推荐安装。
3. 开启Beautiful Soup 之旅
在这里先分享官方文档链接,不过内容是有些多,也不够条理,在此本文章做一下整理方便大家参考。
官方文档
4. 创建 Beautiful Soup 对象
?
| 1 |
from bs4 import BeautifulSoup
|
?
| 1 2 3 4 5 6 7 8 9 10 11 |
html = """
<html><head><title>The Dormouse's story</title></head>
<body>
<p class="title" name="dromouse"><b>The Dormouse's story</b></p>
<p class="story">Once upon a time there were three little sisters; and their names were
<a href="http://example.com/elsie" class="sister" id="link1"><!-- Elsie --></a>,
<a href="http://example.com/lacie" class="sister" id="link2">Lacie</a> and
<a href="http://example.com/tillie" class="sister" id="link3">Tillie</a>;
and they lived at the bottom of a well.</p>
<p class="story">...</p>
"""
|
?
| 1 |
soup = BeautifulSoup(html)
|
?
| 1 |
soup = BeautifulSoup(open('index.html'))
|
上面这句代码便是将本地 index.html 文件打开,用它来创建 soup 对象
?
| 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 |
print soup.prettify()
<html>
<head>
<title>
The Dormouse's story
</title>
</head>
<body>
<p class="title" name="dromouse">
<b>
The Dormouse's story
</b>
</p>
<p class="story">
Once upon a time there were three little sisters; and their names were
<a class="sister" href="http://example.com/elsie" id="link1">
<!-- Elsie -->
</a>
,
<a class="sister" href="http://example.com/lacie" id="link2">
Lacie
</a>
and
<a class="sister" href="http://example.com/tillie" id="link3">
Tillie
</a>
;
and they lived at the bottom of a well.
</p>
<p class="story">
...
</p>
</body>
</html>
|
以上便是输出结果,格式化打印出了它的内容,这个函数经常用到,小伙伴们要记好咯。
5. 四大对象种类
Beautiful Soup将复杂HTML文档转换成一个复杂的树形结构,每个节点都是Python对象,所有对象可以归纳为4种:
- Tag
- NavigableString
- BeautifulSoup
- Comment
下面我们进行一一介绍
(1)Tag
?
| 1 2 3 |
<title>The Dormouse's story</title>
<a class="sister" href="http://example.com/elsie" id="link1">Elsie</a>
|
上面的 title a 等等 HTML 标签加上里面包括的内容就是 Tag,下面我们来感受一下怎样用 Beautiful Soup 来方便地获取 Tags
?
| 1 2 3 4 5 6 7 8 9 10 11 |
print soup.title
#<title>The Dormouse's story</title>
print soup.head
#<head><title>The Dormouse's story</title></head>
print soup.a
#<a class="sister" href="http://example.com/elsie" id="link1"><!-- Elsie --></a>
print soup.p
#<p class="title" name="dromouse"><b>The Dormouse's story</b></p>
|
我们可以利用 soup加标签名轻松地获取这些标签的内容,是不是感觉比正则表达式方便多了?不过有一点是,它查找的是在所有内容中的第一个符合要求的标签,如果要查询所有的标签,我们在后面进行介绍。
?
| 1 2 |
print type(soup.a)
#<class 'bs4.element.Tag'>
|
对于 Tag,它有两个重要的属性,是 name 和 attrs,下面我们分别来感受一下
?
| 1 2 3 4 5 6 |
name
print soup.name
print soup.head.name
#[document]
#head
|
soup 对象本身比较特殊,它的 name 即为 [document],对于其他内部标签,输出的值便为标签本身的名称。
?
| 1 2 3 4 |
attrs
print soup.p.attrs
#{'class': ['title'], 'name': 'dromouse'}
|
在这里,我们把 p 标签的所有属性打印输出了出来,得到的类型是一个字典。
?
| 1 2 |
print soup.p['class']
#['title']
|
?
| 1 2 |
print soup.p.get('class')
#['title']
|
?
| 1 2 3 |
soup.p['class']="newClass"
print soup.p
#<p class="newClass" name="dromouse"><b>The Dormouse's story</b></p>
|
?
| 1 2 3 |
del soup.p['class']
print soup.p
#<p name="dromouse"><b>The Dormouse's story</b></p>
|
不过,对于修改删除的操作,不是我们的主要用途,在此不做详细介绍了,如果有需要,请查看前面提供的官方文档
(2)NavigableString
?
| 1 2 |
print soup.p.string
#The Dormouse's story
|
?
| 1 2 |
print type(soup.p.string)
#<class 'bs4.element.NavigableString'>
|
?
| 1 2 |
print type(soup.p.string)
#<class 'bs4.element.NavigableString'>
|
(3)BeautifulSoup
?
| 1 2 3 4 5 6 |
print type(soup.name)
#<type 'unicode'>
print soup.name
# [document]
print soup.attrs
#{} 空字典
|
(4)Comment
Comment 对象是一个特殊类型的 NavigableString 对象,其实输出的内容仍然不包括注释符号,但是如果不好好处理它,可能会对我们的文本处理造成意想不到的麻烦。
?
| 1 2 3 |
print soup.a
print soup.a.string
print type(soup.a.string)
|
?
| 1 2 3 |
<a class="sister" href="http://example.com/elsie" id="link1"><!-- Elsie --></a>
Elsie
<class 'bs4.element.Comment'>
|
a 标签里的内容实际上是注释,但是如果我们利用 .string 来输出它的内容,我们发现它已经把注释符号去掉了,所以这可能会给我们带来不必要的麻烦。
?
| 1 2 |
if type(soup.a.string)==bs4.element.Comment:
print soup.a.string
|
上面的代码中,我们首先判断了它的类型,是否为 Comment 类型,然后再进行其他操作,如打印输出。
6. 遍历文档树
(1)直接子节点
要点:.contents .children 属性
?
| 1 2 |
print soup.head.contents
#[<title>The Dormouse's story</title>]
|
?
| 1 2 3 4 |
print soup.head.contents[0]
#<title>The Dormouse's story</title>
.children
|
它返回的不是一个 list,不过我们可以通过遍历获取所有子节点。
?
| 1 2 |
print soup.head.children
#<listiterator object at 0x7f71457f5710>
|
?
| 1 2 3 4 5 6 7 8 9 10 11 12 |
for child in soup.body.children:
print child
<p class="title" name="dromouse"><b>The Dormouse's story</b></p>
<p class="story">Once upon a time there were three little sisters; and their names were
<a class="sister" href="http://example.com/elsie" id="link1"><!-- Elsie --></a>,
<a class="sister" href="http://example.com/lacie" id="link2">Lacie</a> and
<a class="sister" href="http://example.com/tillie" id="link3">Tillie</a>;
and they lived at the bottom of a well.</p>
<p class="story">...</p>
|
(2)所有子孙节点
知识点:.descendants 属性
.descendants
?
| 1 2 |
for child in soup.descendants:
print child
|
?
| 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 |
<html><head><title>The Dormouse's story</title></head>
<body>
<p class="title" name="dromouse"><b>The Dormouse's story</b></p>
<p class="story">Once upon a time there were three little sisters; and their names were
<a class="sister" href="http://example.com/elsie" id="link1"><!-- Elsie --></a>,
<a class="sister" href="http://example.com/lacie" id="link2">Lacie</a> and
<a class="sister" href="http://example.com/tillie" id="link3">Tillie</a>;
and they lived at the bottom of a well.</p>
<p class="story">...</p>
</body></html>
<head><title>The Dormouse's story</title></head>
<title>The Dormouse's story</title>
The Dormouse's story
<body>
<p class="title" name="dromouse"><b>The Dormouse's story</b></p>
<p class="story">Once upon a time there were three little sisters; and their names were
<a class="sister" href="http://example.com/elsie" id="link1"><!-- Elsie --></a>,
<a class="sister" href="http://example.com/lacie" id="link2">Lacie</a> and
<a class="sister" href="http://example.com/tillie" id="link3">Tillie</a>;
and they lived at the bottom of a well.</p>
<p class="story">...</p>
</body>
<p class="title" name="dromouse"><b>The Dormouse's story</b></p>
<b>The Dormouse's story</b>
The Dormouse's story
<p class="story">Once upon a time there were three little sisters; and their names were
<a class="sister" href="http://example.com/elsie" id="link1"><!-- Elsie --></a>,
<a class="sister" href="http://example.com/lacie" id="link2">Lacie</a> and
<a class="sister" href="http://example.com/tillie" id="link3">Tillie</a>;
and they lived at the bottom of a well.</p>
Once upon a time there were three little sisters; and their names were
<a class="sister" href="http://example.com/elsie" id="link1"><!-- Elsie --></a>
Elsie
,
<a class="sister" href="http://example.com/lacie" id="link2">Lacie</a>
Lacie
and
<a class="sister" href="http://example.com/tillie" id="link3">Tillie</a>
Tillie
;
and they lived at the bottom of a well.
<p class="story">...</p>
...
|
(3)节点内容
知识点:.string 属性
如果tag只有一个 NavigableString 类型子节点,那么这个tag可以使用 .string 得到子节点。如果一个tag仅有一个子节点,那么这个tag也可以使用 .string 方法,输出结果与当前唯一子节点的 .string 结果相同。
?
| 1 2 3 4 |
print soup.head.string
#The Dormouse's story
print soup.title.string
#The Dormouse's story
|
?
| 1 2 |
print soup.html.string
# None
|
(4)多个内容
知识点: .strings .stripped_strings 属性
.strings
?
| 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 |
for string in soup.strings:
print(repr(string))
# u"The Dormouse's story"
# u'\n\n'
# u"The Dormouse's story"
# u'\n\n'
# u'Once upon a time there were three little sisters; and their names were\n'
# u'Elsie'
# u',\n'
# u'Lacie'
# u' and\n'
# u'Tillie'
# u';\nand they lived at the bottom of a well.'
# u'\n\n'
# u'...'
# u'\n'
|
.stripped_strings
?
| 1 2 3 4 5 6 7 8 9 10 11 12 |
for string in soup.stripped_strings:
print(repr(string))
# u"The Dormouse's story"
# u"The Dormouse's story"
# u'Once upon a time there were three little sisters; and their names were'
# u'Elsie'
# u','
# u'Lacie'
# u'and'
# u'Tillie'
# u';\nand they lived at the bottom of a well.'
# u'...'
|
(5)父节点
知识点: .parent 属性
?
| 1 2 3 4 5 6 7 |
p = soup.p
print p.parent.name
#body
content = soup.head.title.string
print content.parent.name
#title
|
(6)全部父节点
知识点:.parents 属性
?
| 1 2 3 |
content = soup.head.title.string
for parent in content.parents:
print parent.name
|
?
| 1 2 3 4 |
title
head
html
[document]
|
(7)兄弟节点
知识点:.next_sibling .previous_sibling 属性
兄弟节点可以理解为和本节点处在统一级的节点,.next_sibling 属性获取了该节点的下一个兄弟节点,.previous_sibling 则与之相反,如果节点不存在,则返回 None
?
| 1 2 3 4 5 6 7 8 9 10 11 |
print soup.p.next_sibling
# 实际该处为空白
print soup.p.prev_sibling
#None 没有前一个兄弟节点,返回 None
print soup.p.next_sibling.next_sibling
#<p class="story">Once upon a time there were three little sisters; and their names were
#<a class="sister" href="http://example.com/elsie" id="link1"><!-- Elsie --></a>,
#<a class="sister" href="http://example.com/lacie" id="link2">Lacie</a> and
#<a class="sister" href="http://example.com/tillie" id="link3">Tillie</a>;
#and they lived at the bottom of a well.</p>
#下一个节点的下一个兄弟节点是我们可以看到的节点
|
(8)全部兄弟节点
知识点:.next_siblings .previous_siblings 属性
?
| 1 2 3 4 5 6 7 8 |
for sibling in soup.a.next_siblings:
print(repr(sibling))
# u',\n'
# <a class="sister" href="http://example.com/lacie" id="link2">Lacie</a>
# u' and\n'
# <a class="sister" href="http://example.com/tillie" id="link3">Tillie</a>
# u'; and they lived at the bottom of a well.'
# None
|
(9)前后节点
知识点:.next_element .previous_element 属性
与 .next_sibling .previous_sibling 不同,它并不是针对于兄弟节点,而是在所有节点,不分层次
比如 head 节点为
<head><title>The Dormouse's story</title></head>
?
| 1 2 |
print soup.head.next_element
#<title>The Dormouse's story</title>
|
(10)所有前后节点
知识点:.next_elements .previous_elements 属性
?
| 1 2 3 4 5 6 7 8 9 |
for element in last_a_tag.next_elements:
print(repr(element))
# u'Tillie'
# u';\nand they lived at the bottom of a well.'
# u'\n\n'
# <p class="story">...</p>
# u'...'
# u'\n'
# None
|
7.搜索文档树
(1)find_all( name , attrs , recursive , text , kwargs )
find_all() 方法搜索当前tag的所有tag子节点,并判断是否符合过滤器的条件
1)name 参数
name 参数可以查找所有名字为 name 的tag,字符串对象会被自动忽略掉
A.传字符串
最简单的过滤器是字符串.在搜索方法中传入一个字符串参数,Beautiful Soup会查找与字符串完整匹配的内容,下面的例子用于查找文档中所有的<b>标签
?
| 1 2 3 4 5 |
soup.find_all('b')
# [<b>The Dormouse's story</b>]
print soup.find_all('a')
#[<a class="sister" href="http://example.com/elsie" id="link1"><!-- Elsie --></a>, <a class="sister" href="http://example.com/lacie" id="link2">Lacie</a>, <a class="sister" href="http://example.com/tillie" id="link3">Tillie</a>]
|
B.传正则表达式
?
| 1 2 3 4 5 |
import re
for tag in soup.find_all(re.compile("^b")):
print(tag.name)
# body
# b
|
C.传列表
?
| 1 2 3 4 5 |
soup.find_all(["a", "b"])
# [<b>The Dormouse's story</b>,
# <a class="sister" href="http://example.com/elsie" id="link1">Elsie</a>,
# <a class="sister" href="http://example.com/lacie" id="link2">Lacie</a>,
# <a class="sister" href="http://example.com/tillie" id="link3">Tillie</a>]
|
D.传 True
?
| 1 2 3 4 5 6 7 8 9 10 11 |
for tag in soup.find_all(True):
print(tag.name)
# html
# head
# title
# body
# p
# b
# p
# a
# a
|
E.传方法
如果没有合适过滤器,那么还可以定义一个方法,方法只接受一个元素参数 [4] ,如果这个方法返回 True 表示当前元素匹配并且被找到,如果不是则反回 False
?
| 1 2 |
def has_class_but_no_id(tag):
return tag.has_attr('class') and not tag.has_attr('id')
|
?
| 1 2 3 4 |
soup.find_all(has_class_but_no_id)
# [<p class="title"><b>The Dormouse's story</b></p>,
# <p class="story">Once upon a time there were...</p>,
# <p class="story">...</p>]
|
2)keyword 参数
注意:如果一个指定名字的参数不是搜索内置的参数名,搜索时会把该参数当作指定名字tag的属性来搜索,如果包含一个名字为 id 的参数,Beautiful Soup会搜索每个tag的”id”属性
?
| 1 2 |
soup.find_all(id='link2')
# [<a class="sister" href="http://example.com/lacie" id="link2">Lacie</a>]
|
?
| 1 2 |
soup.find_all(href=re.compile("elsie"))
# [<a class="sister" href="http://example.com/elsie" id="link1">Elsie</a>]
|
?
| 1 2 |
soup.find_all(href=re.compile("elsie"), id='link1')
# [<a class="sister" href="http://example.com/elsie" id="link1">three</a>]
|
?
| 1 2 3 4 |
soup.find_all("a", class_="sister")
# [<a class="sister" href="http://example.com/elsie" id="link1">Elsie</a>,
# <a class="sister" href="http://example.com/lacie" id="link2">Lacie</a>,
# <a class="sister" href="http://example.com/tillie" id="link3">Tillie</a>]
|
?
| 1 2 3 4 |
soup.find_all("a", class_="sister")
# [<a class="sister" href="http://example.com/elsie" id="link1">Elsie</a>,
# <a class="sister" href="http://example.com/lacie" id="link2">Lacie</a>,
# <a class="sister" href="http://example.com/tillie" id="link3">Tillie</a>]
|
?
| 1 2 |
data_soup.find_all(attrs={
"data-foo": "value"})
# [<div data-foo="value">foo!</div>]
|
3)text 参数
?
| 1 2 3 4 5 6 7 8 |
soup.find_all(text="Elsie")
# [u'Elsie']
soup.find_all(text=["Tillie", "Elsie", "Lacie"])
# [u'Elsie', u'Lacie', u'Tillie']
soup.find_all(text=re.compile("Dormouse"))
[u"The Dormouse's story", u"The Dormouse's story"]
|
4)limit 参数
find_all() 方法返回全部的搜索结构,如果文档树很大那么搜索会很慢.如果我们不需要全部结果,可以使用 limit 参数限制返回结果的数量.效果与SQL中的limit关键字类似,当搜索到的结果数量达到 limit 的限制时,就停止搜索返回结果.
?
| 1 2 3 |
soup.find_all("a", limit=2)
# [<a class="sister" href="http://example.com/elsie" id="link1">Elsie</a>,
# <a class="sister" href="http://example.com/lacie" id="link2">Lacie</a>]
|
5)recursive 参数
调用tag的 find_all() 方法时,Beautiful Soup会检索当前tag的所有子孙节点,如果只想搜索tag的直接子节点,可以使用参数 recursive=False .
一段简单的文档:
复制代码代码如下:
<html>
<head>
<title>
The Dormouse's story
</title>
</head>
...
?
| 1 2 3 4 5 |
soup.html.find_all("title")
# [<title>The Dormouse's story</title>]
soup.html.find_all("title", recursive=False)
# []
|
(2)find( name , attrs , recursive , text , kwargs )
它与 find_all() 方法唯一的区别是 find_all() 方法的返回结果是值包含一个元素的列表,而 find() 方法直接返回结果
(3)find_parents() find_parent()
find_all() 和 find() 只搜索当前节点的所有子节点,孙子节点等. find_parents() 和 find_parent() 用来搜索当前节点的父辈节点,搜索方法与普通tag的搜索方法相同,搜索文档搜索文档包含的内容
(4)find_next_siblings() find_next_sibling()
这2个方法通过 .next_siblings 属性对当 tag 的所有后面解析的兄弟 tag 节点进行迭代, find_next_siblings() 方法返回所有符合条件的后面的兄弟节点,find_next_sibling() 只返回符合条件的后面的第一个tag节点
(5)find_previous_siblings() find_previous_sibling()
这2个方法通过 .previous_siblings 属性对当前 tag 的前面解析的兄弟 tag 节点进行迭代, find_previous_siblings() 方法返回所有符合条件的前面的兄弟节点, find_previous_sibling() 方法返回第一个符合条件的前面的兄弟节点
(6)find_all_next() find_next()
这2个方法通过 .next_elements 属性对当前 tag 的之后的 tag 和字符串进行迭代, find_all_next() 方法返回所有符合条件的节点, find_next() 方法返回第一个符合条件的节点
(7)find_all_previous() 和 find_previous()
这2个方法通过 .previous_elements 属性对当前节点前面的 tag 和字符串进行迭代, find_all_previous() 方法返回所有符合条件的节点, find_previous()方法返回第一个符合条件的节点
注:以上(2)(3)(4)(5)(6)(7)方法参数用法与 find_all() 完全相同,原理均类似,在此不再赘述。
8.CSS选择器
我们在写 CSS 时,标签名不加任何修饰,类名前加点,id名前加 #,在这里我们也可以利用类似的方法来筛选元素,用到的方法是 soup.select(),返回类型是 list
(1)通过标签名查找
?
| 1 2 3 4 5 6 7 8 |
print soup.select('title')
#[<title>The Dormouse's story</title>]
print soup.select('a')
#[<a class="sister" href="http://example.com/elsie" id="link1"><!-- Elsie --></a>, <a class="sister" href="http://example.com/lacie" id="link2">Lacie</a>, <a class="sister" href="http://example.com/tillie" id="link3">Tillie</a>]
print soup.select('b')
#[<b>The Dormouse's story</b>]
|
(2)通过类名查找
?
| 1 2 |
print soup.select('.sister')
#[<a class="sister" href="http://example.com/elsie" id="link1"><!-- Elsie --></a>, <a class="sister" href="http://example.com/lacie" id="link2">Lacie</a>, <a class="sister" href="http://example.com/tillie" id="link3">Tillie</a>]
|
(3)通过 id 名查找
?
| 1 2 |
print soup.select('#link1')
#[<a class="sister" href="http://example.com/elsie" id="link1"><!-- Elsie --></a>]
|
(4)组合查找
?
| 1 2 |
print soup.select('p #link1')
#[<a class="sister" href="http://example.com/elsie" id="link1"><!-- Elsie --></a>]
|
?
| 1 2 |
print soup.select("head > title")
#[<title>The Dormouse's story</title>]
|
(5)属性查找
?
| 1 2 3 4 5 |
print soup.select("head > title")
#[<title>The Dormouse's story</title>]
print soup.select('a[href="http://example.com/elsie"]')
#[<a class="sister" href="http://example.com/elsie" id="link1"><!-- Elsie --></a>]
|
?
| 1 2 |
print soup.select('p a[href="http://example.com/elsie"]')
#[<a class="sister" href="http://example.com/elsie" id="link1"><!-- Elsie --></a>]
|
好,这就是另一种与 find_all 方法有异曲同工之妙的查找方法,是不是感觉很方便?
总结
本篇内容比较多,把 Beautiful Soup 的方法进行了大部分整理和总结,不过这还不算完全,仍然有 Beautiful Soup 的修改删除功能,不过这些功能用得比较少,只整理了查找提取的方法,希望对大家有帮助!小伙伴们加油!
熟练掌握了 Beautiful Soup,一定会给你带来太多方便,加油吧!

版权声明:本文内容由互联网用户自发贡献,该文观点仅代表作者本人。本站仅提供信息存储空间服务,不拥有所有权,不承担相关法律责任。如发现本站有涉嫌侵权/违法违规的内容,请联系我们,一经查实,本站将立刻删除。
如需转载请保留出处:https://51itzy.com/kjqy/132240.html